In Part 1, we asked three questions:
- Did the transfer complete?
- Is it safe for the client to retry the request?
- What happens if the transfer completed before the crash, but the client never received the response?
These questions highlight an important reliability problem. When something fails, the application needs to handle the transaction without losing it or processing it more than once.
A banking application may also depend on external services. What happens if one of those services is temporarily unavailable? Should the transaction be retried? And what should happen if the transaction itself is invalid?
In this part, we’ll look at three scenarios:
- temporary failures,
- permanent failures, and
- duplicate message delivery.
We’ll handle them using the retry queue, dead-letter queue, acknowledgements, and idempotent transaction processing introduced in our banking application.
Temporary failures
Consider a transaction that depends on an external banking service. That service might be temporarily unavailable when the worker tries to process the transaction.
Retrying later may succeed. But immediately processing the same transaction again isn’t necessarily useful. Instead, when the worker detects a retryable failure, it asks the broker layer to send the transaction to the retry queue.
await broker.retry(
  transaction,
  retries + 1
);

broker.acknowledge(message);
The worker then returns and can continue processing other transactions. The retry count is stored with the message so the application can keep track of how many attempts have already been made. The important separation here is that the worker decides whether the transaction should be retried, while broker.js handles publishing it to the appropriate LavinMQ queue.
Delaying the retry
The retry queue we created in Part 1 has a five-second message TTL. When the worker sends a transaction to this queue, LavinMQ holds it there for five seconds. When the TTL expires, the message is routed back to the main transaction queue, where the worker can receive it again.
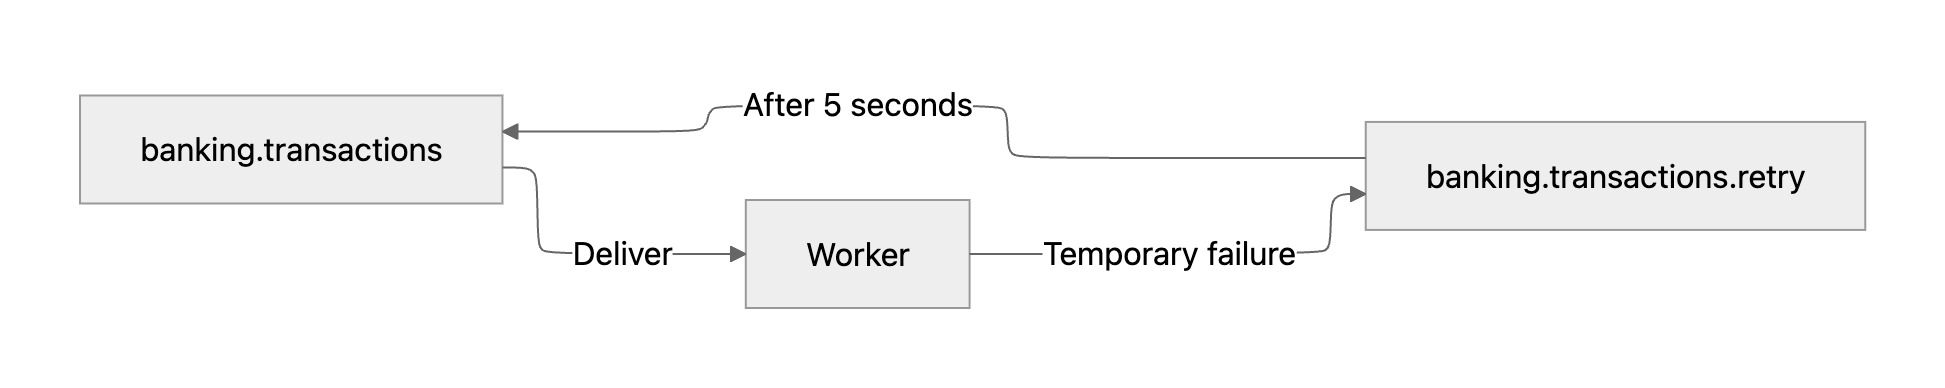
This keeps the retry delay outside the worker. The worker doesn’t need to wait, sleep, or repeatedly poll for the transaction. It can continue processing other messages while LavinMQ handles the delay.
Limiting retries
A temporary problem might not remain temporary forever. If an external service stays unavailable, retrying indefinitely could cause the same transaction to cycle through the queues without ever being resolved.
That’s why the worker keeps track of the retry count.
const retries = Number(
  message.properties.headers?.["x-retry-count"] || 0
);
When processing fails, the worker checks both whether the failure is retryable and whether the maximum number of retries has been reached.
if (
  error.retryable &&
  retries < config.maxRetries
) {
  await broker.retry(
    transaction,
    retries + 1
  );

  broker.acknowledge(message);
  return;
}
If the failure is retryable and the retry limit hasn’t been reached, the transaction goes back through the retry path. Once the maximum number of retries is reached, it follows the permanent-failure path instead.
Try it: temporary failure
Start the worker:
npm run worker:amqplib
Start the publisher in another terminal and publish a transaction that simulates a temporary failure:
npm run producer:amqplib -- temporary-failure
The worker attempts to process the transaction and encounters a temporary failure. It sends the transaction to the retry queue. After five seconds, LavinMQ routes it back to the main queue, where the worker receives it again.
The worker repeats this process until the maximum retry count is reached. After that, the transaction is sent to the dead-letter queue. This demonstrates how LavinMQ can handle the retry delay while the worker continues processing other messages.
Permanent failures
Retries make sense only when there is a reasonable chance that another attempt will succeed. Some failures are permanent.
For example, a transaction with a negative amount will still be invalid five seconds later. Retrying it won’t solve the problem. The same applies to a transaction that requires manual review.
When the worker determines that a transaction shouldn’t be retried, it asks the broker layer to send it to the dead-letter path:
await broker.sendToDeadQueue(
  transaction,
  error,
  retries
);

broker.acknowledge(message);
Again, the responsibilities are separated. The worker decides that the transaction should no longer be retried. The broker layer handles how it is published to the dead-letter exchange.
The dead-letter exchange routes the failed transaction to the dead-letter queue, where it can be inspected later. The original message is then acknowledged so LavinMQ knows that the worker has finished handling it.
The dead-letter queue therefore gives us a place to keep transactions that should no longer be processed automatically.
Try it: permanent failure
Start the worker:
npm run worker:amqplib
Start the publisher in another terminal and publish an invalid transaction:
npm run producer:amqplib -- invalid
Because the transaction contains an invalid amount, the worker doesn’t retry it. Instead, it sends the transaction through the broker layer to the dead-letter path.
You can also try the manual-review scenario:
npm run producer:amqplib -- review
This transaction follows the same path because it shouldn’t be automatically retried. The failed transactions can then be inspected in the dead-letter queue.
Making transaction processing idempotent
Retries solve one part of the reliability problem, but there’s another case we need to consider: duplicate message delivery.
A message can be delivered more than once. For example, imagine the worker successfully processes a transaction and saves the result, but its connection disappears before the acknowledgement reaches LavinMQ. From the broker’s perspective, the message hasn’t been acknowledged, so it can become available for delivery again. That creates an important question.
What happens if we process the same banking transaction twice?
This is why every transaction in our example has a unique transactionId. Before processing a transaction, the worker checks whether that transaction has already been processed.
if (hasProcessed(transaction.transactionId)) {
  log(
    "Transaction already processed, acknowledging message",
    {
      transactionId: transaction.transactionId,
    }
  );

  broker.acknowledge(message);
  return;
}
If the transaction has already been processed, the worker doesn’t process it again. It simply acknowledges the message. If it hasn’t been processed, the worker continues normally.
const result =
  await processTransaction(transaction);

saveResult(
  transaction.transactionId,
  result
);

broker.acknowledge(message);
This is the basic idea behind idempotent processing — receiving the same transaction message more than once shouldn’t cause the banking operation to be performed more than once. Acknowledgements help with reliable message delivery, but they don’t by themselves guarantee exactly-once transaction processing. The application still needs to account for duplicate deliveries.
The important part is that the application logic and messaging operations remain separated.
The worker decides:
- whether processing succeeded,
- whether a failure is retryable,
- whether the retry limit has been reached, and
- whether a transaction has already been processed.
The broker layer handles:
- publishing messages,
- subscribing to the transaction queue,
- acknowledgements,
- publishing retries,
- publishing permanent failures, and
- communication with LavinMQ.
This is the same separation we introduced in Part 1.
What’s next?
The banking application can now handle three important failure scenarios:
- Temporary failures are sent to the retry queue and attempted again after a delay.
- Permanent failures are sent to the dead-letter queue for later investigation.
- Duplicate deliveries are handled through idempotent transaction processing.
Together, these patterns make transaction processing more resilient when things go wrong.
But failure handling doesn’t stop at message processing. The connection between the application and LavinMQ can fail too.
What happens when that connection is lost? How does the consumer recover? And does the Node.js AMQP client we choose change how much recovery logic we need to implement ourselves?
In Part 3, we’ll compare amqplib and amqp-client.js, focusing on connection recovery, consumer recovery, and the responsibilities each client leaves to the application.
 Hailay Gebremeskel